Working with Claude Code and Matt Pocock’s skills to evaluate RAG vs Document Stuffing for natural language search of single legal PDF documents.
Let’s try to do this one properly from the beginning* using Matt Pocock’s skills.

My slightly disorganised initial spec…

Still amazes me how good AI is regurgitating an input in a way that makes it seem like it actually understands what has been sent. Although this is supposed to be sent to the console one question at a time to make it easy to reply*.

… although the Q3 question had a weird human-like typo ‘standardize one the Claude API’, rather than ‘standardize on the Claude API’
For some reason* it sent all the questions in one output so I had to reply in this messy format:

Some more questions from Claude:

Option 2 chosen, I don’t want confusing files littering the filesystem.
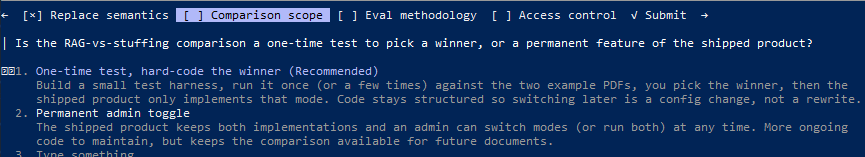
Option 2 chosen as I want the client to test this.
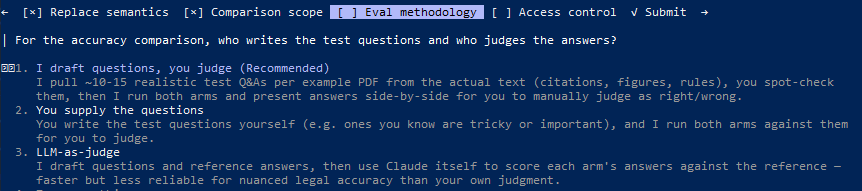
Option 3 chosen here because I want the LLM to do the testing and report back before I ask the client to test to see how their results compare.

Option 2 chosen because eventually there will be admin and user logins for this.
Second round of questions from Claude:
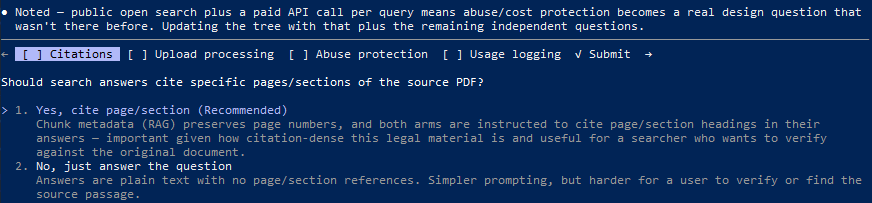
Citations are very important in this project

Wasn’t sure here. Usability vs complexity. Went with 1 for now.

Chose 2 because we want to see the LLM costs as well.
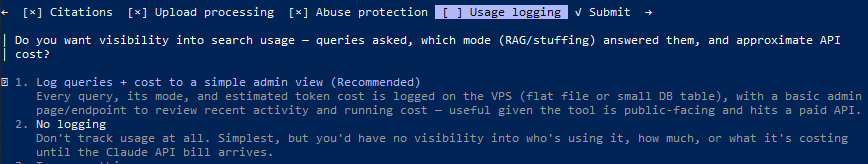
Chose 1.
Third round of questions from Claude
I’m starting to see why people like to do ‘single prompt’ vibe coding 😅

Option 1 – I need to be able to compare for a while as this is the beginning of a new system

Choose option 1 for now. There were a couple of questions about whether I have API keys as well.
Claude also wants to make sure I remember who made the decisions if it all goes wrong later and I look for something to blame…

(chose yes)
Next, Claude did some set up stuff for the VPS that I don’t want to publish here. Last question.

Normally with something that needs lots of iterative testing I wouldn’t bother with Git until nearer the end but because I want to use the /to-spec skill…

Hmmm, it’s got confused and wants to run /to-spec now without deciding how to approach deploying. Let’s go with /to-spec and see what happens.
*Oh… Looks like I forgot a step right at the beginning which is maybe why the /grill-me-with-docs didn’t work as expected. Good to know and remember for the next project…


Hopefully we are back on track.

Another question. Had to ask chatGPT what this meant!

Basically, do the tests without real API calls and the stuff on the frontend doesn’t need testing to start.
Anyway.. looks like we are back on course with the first GitHub issue that /to-spec creates

View full initial issue
Problem Statement
Course PDFs currently can’t be searched with natural language without manually building an embeddings index and standing up a whole new dedicated app instance per document — that’s how the existing pdf-search-app deployments on the VPS work today (one Docker container per document, each with its own hand-built index). There’s also no way to know, for documents of this size and density, whether retrieval-augmented generation (RAG) actually beats simply sending the whole document to the model on every query (“Stuffing”) — nobody has compared them side by side.
Solution
A single-active-document search tool. An Admin uploads a PDF, which becomes the one “Active Document” (uploading again fully replaces it — there is never more than one). Anyone can then ask natural-language questions about the Active Document without logging in, and get an answer that cites the page/section it came from. Behind the scenes, the Admin can choose which Retrieval Mode (RAG or Stuffing) serves those public answers, and can use an admin-only Compare View to run any query through both modes side by side to judge quality — most usefully right after replacing the Active Document. All processing lives behind a VPS-hosted HTTP API; the existing cPanel install hosts only a thin, logic-free frontend that talks to that API.
User Stories
- As an Admin, I want to upload a new PDF, so that I can make a new course document searchable.
- As an Admin, I want uploading a new PDF to fully replace whatever was previously the Active Document, so that there’s never ambiguity about which document is being searched.
- As an Admin, I want upload/replace to complete synchronously and tell me success or failure before I leave the page, so that I don’t have to guess whether processing finished.
- As an Admin, I want to authenticate before I can replace the Active Document or change settings, so that random visitors can’t overwrite the course material or its configuration.
- As an Admin, I want upload to reject files that aren’t valid PDFs or that fail text extraction, so that the Active Document is never left in a broken state.
- As an Admin, I want to choose which Retrieval Mode (RAG or Stuffing) answers public queries, so that I can put whichever mode performs best into production.
- As an Admin, I want to see which Retrieval Mode is currently live before I change it, so that I don’t accidentally serve a mode I didn’t intend to.
- As an Admin, I want a Compare View where I submit one query and see both modes’ answers side by side, so that I can judge quality after replacing the Active Document, without affecting what public Searchers see.
- As an Admin, I want to see recent search queries, which mode answered each one, and their estimated cost, so that I have visibility into usage and spend.
- As a Searcher, I want to ask a natural-language question about the Active Document without logging in, so that I can quickly find information in the course material.
- As a Searcher, I want the answer to cite the page/section of the source PDF it came from, so that I can verify it against the original document.
- As a Searcher, I want a clear message if there’s no Active Document yet, so that I understand there’s nothing to search.
- As a Searcher, I want a clear error if I’ve been rate-limited, so that I understand why my query didn’t go through.
- As the system operator, I want public search requests capped by a per-IP rate limit (10/min), so that the tool can’t be abused into runaway API costs.
- As the system operator, I want a hard daily spend cap ($5/day) on Claude + Voyage usage, so that a traffic spike or abuse can’t produce a surprise bill; once hit, search returns a clear error until the cap resets.
- As the system operator, I want all PDF processing, retrieval logic, and LLM/embedding calls to live on the VPS behind HTTP endpoints, so that the cPanel frontend can remain a thin, logic-free presentation layer (ADR-0001).
- As the system operator, I want replacing the Active Document to discard the old PDF file, extracted text, and embeddings outright, so that there’s no leftover data or version history to manage (ADR-0002).
- As a developer evaluating the two modes, I want a small set of test questions and reference answers drawn from each of the two example PDFs, so that I can objectively compare RAG vs Stuffing before choosing a production default.
- As a developer evaluating the two modes, I want Claude used as an LLM judge to score each mode’s answer against the reference answer, so that I get a repeatable, low-effort accuracy signal without hand-grading every case.
- As a developer, I want the RAG mode to use Voyage’s voyage-law-2 embedding model, so that embeddings are tuned for this legal/costs-law content.
- As a developer, I want both Retrieval Modes to generate answers with Claude Sonnet 5, so that the comparison isolates retrieval strategy as the only variable.
- As the system operator, I want the search endpoint open to any visitor while upload/replace and all admin controls require authentication, so that the tool is easy for course participants to use while the content pipeline stays protected.
- As an Admin, I want the Anthropic API key, Voyage API key, and admin credentials configured via environment variables, so that secrets are never hardcoded or committed to source control.
- As the system operator, I want this new service isolated on its own port and directory on the VPS, so that it never interferes with the existing pdf-search-app containers or the video-rag stack, which stay running untouched.
Implementation Decisions
- New service (“the API”) built as a Node.js/Express app, containerized with Docker — consistent with the existing proven pattern already running on this VPS, but deployed to a new directory and a new port (8084), fully isolated from the existing pdf-search-app containers (8081-8083) and video-rag (80). No changes to those existing deployments.
- Exactly one Active Document exists at a time (per CONTEXT.md). Storage for its extracted text and, in RAG mode, its chunk+embedding index, is flat files on disk in the container’s data volume — no external database, given the single-document scale (contrast with video-rag’s Postgres/pgvector, which suits a different scale).
- Two Retrieval Modes are both implemented and always available: RAG (chunk + embed via voyage-law-2, retrieve top-k relevant chunks, page-number metadata preserved per chunk) and Stuffing (full extracted text, page-marked, sent on every query). Both use Claude Sonnet 5 for generation and are prompted to cite page/section in every answer.
- Retrieval Mode is a single global admin-set config value that determines which mode answers public search requests. A separate admin-only Compare endpoint/view runs a given query through both modes and returns both answers without changing the global config.
- Two access tiers: public/unauthenticated for search, and an authenticated admin tier (shared credential/token) gating replace, mode changes, the Compare View, and the usage log view.
- Rate limiting: 10 requests/minute per IP on the public search endpoint. A running daily spend counter (reset at UTC midnight) tracks estimated Claude + Voyage cost; once it exceeds $5/day, search requests are rejected with a clear error until reset.
- Usage logging: every search request is logged (timestamp, query text, mode used, estimated cost) to a simple on-disk log, readable via the admin usage view.
- Conceptual endpoints (not literal routes/files, to be decided during implementation): public search, public status (whether an Active Document exists and its title), admin replace (PDF upload), admin set-mode, admin compare, admin usage log.
- The cPanel-hosted frontend is static HTML/JS (optionally light PHP) with no server-side logic; it calls the VPS API directly from the browser. CORS on the API must allow the cPanel origin.
- A standalone evaluation harness (not part of the shipped product) runs the drafted test Q&As from both example PDFs through both Retrieval Modes and uses Claude as judge against reference answers, producing a report that informs which mode the Admin sets as the production default at launch.
Testing Decisions
- Single test seam: HTTP integration tests against the Express app (the API’s external HTTP boundary), with the Anthropic and Voyage network calls stubbed/mocked so tests are deterministic and don’t spend real API credits or money.
- Test only externally observable behavior: e.g., given an Active Document and a given mode, a search request returns an answer containing an expected citation shape; replace discards prior state and subsequent searches reflect the new document; a mode change changes which mode subsequent searches use; requests beyond the rate limit return 429; requests after the daily cost cap is exceeded return the cap-exceeded error; unauthenticated requests to admin endpoints are rejected.
- No isolated unit tests of chunking/embedding math — covered indirectly through the HTTP-level RAG search tests, per the single-seam preference.
- No prior art in this repo — it’s greenfield; this establishes the first test suite and its conventions.
Out of Scope
- Multi-document library / document selection UI — there is exactly one Active Document, per CONTEXT.md.
- Any changes to the existing pdf-search-app containers or the video-rag stack — both stay running untouched.
- User accounts or per-searcher identity — search is anonymous and open to anyone.
- Version history or rollback of a replaced document (ADR-0002).
- OCR or scanned-PDF support — only native-text PDFs are supported, matching the two example PDFs.
- Video transcript search — this spec is PDF-only.
- Production domain/SSL/cPanel deployment mechanics beyond a working integration — treated as a deployment detail, not part of this spec.
Further Notes
- The two example PDFs in pdfs-original/ (“INTEREST ON COSTS COURSE MATERIAL.pdf” and “FINANCIAL MIS-SELLING AND COSTS COURSE MATERIAL.pdf”) are dense UK costs-law course material, roughly 45-50 pages each, heavy with case citations and cross-references — the primary material for both the eval harness and manual QA.
- voyage-law-2 and Claude Sonnet 5 were independently already in use by the existing pdf-search-app deployment on the same VPS, which gives some confidence in the choice.
- VPS facts relevant to implementation: Debian 12, Docker + Compose v5 already installed, passwordless sudo for the debian user, ports 80 and 8081-8083 already occupied by other containers.
- docs/adr/0001-vps-hosts-all-logic.md and docs/adr/0002-discard-on-replace.md record the two most significant architectural trade-offs behind this spec and should be read before implementation.
let’s try /to-tickets next to see if it can turn the project into sensible steps using GitHub’s issue tracker.
Looking good…

Tickets all created…

Let’s start coding with /implement
The code review from the second issue (the first code creation issue – #2 above) has come in…

Fixes are in and the tests pass this time. Code is deployed and committed and the issue moved to closed.
Ticket #3
The public search endpoint (built in #2) is protected from abuse and runaway cost: a per-IP rate limit of 10 requests/minute, and a running daily spend cap of $5 across Claude + Voyage usage that resets at UTC midnight. Every search request is logged (timestamp, query text, mode used, estimated cost) to a store an authenticated Admin can read back.
also done…
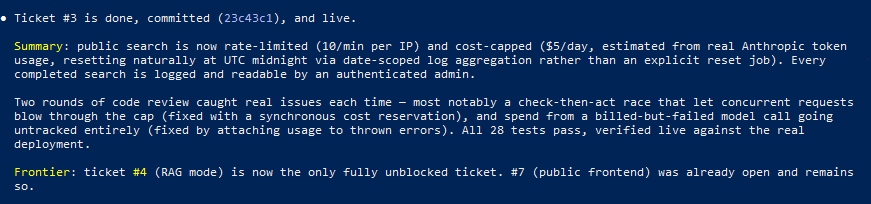
Ticket #4
On upload, the Active Document is also chunked and embedded via Voyage’s voyage-law-2 model, with page-number metadata preserved per chunk, alongside the full-text Stuffing path from #2. An authenticated Admin can set a global Retrieval Mode (Stuffing or RAG); public search then answers using whichever mode is currently active, retrieving the top-k relevant chunks and citing pages when in RAG mode.
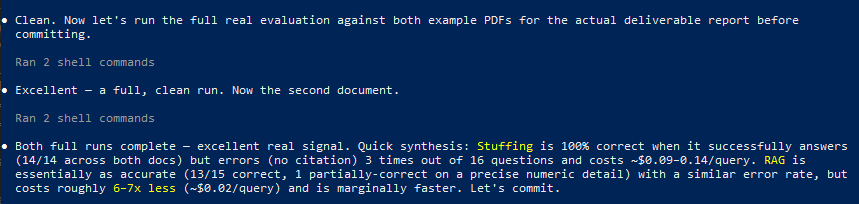
Ooh, ‘stuffing’ seems expensive!


OK, this is really interesting and (assuming it’s correct 😅) shows how useful AI coding is for fast evaluation of two different techniques for a process…
Ticket #5 now done with a bit more info on the two different techniques.

last issue tickets in progress…

Oh… some more questions…

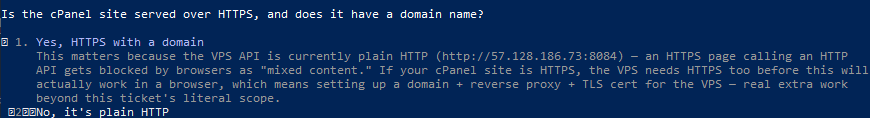
Might need some SSL and DNS work done for the connection between the customer facing site and the endpoints on the VPS…

Checked in the browser using Claude in Chrome:


Ticket #8, one of the things that a human would probably have thought about from the being if architecting this from scratch – CORS for all the endpoints.

Another clever spot by the AI but really shouldn’t have been coded like this from the start…

Uploaded to my cPanel server. Admin looks good…

I’m getting too many errors with this and Claude doesn’t seem to be that bothered. Sometimes this comes back from a query…
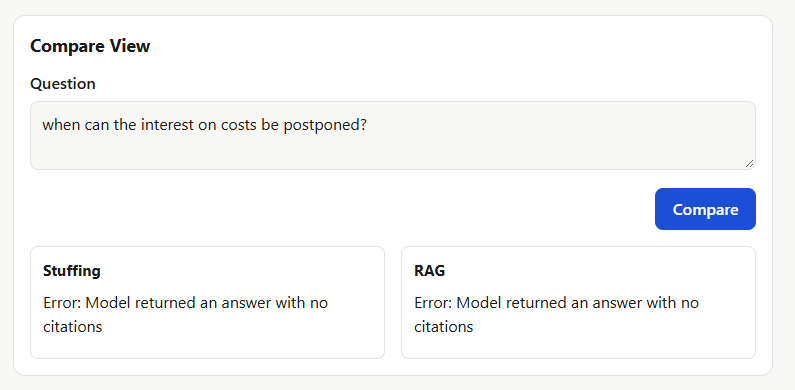

Claude’s answer. Still not sure about this…

Made some changes but it’s still not working well…
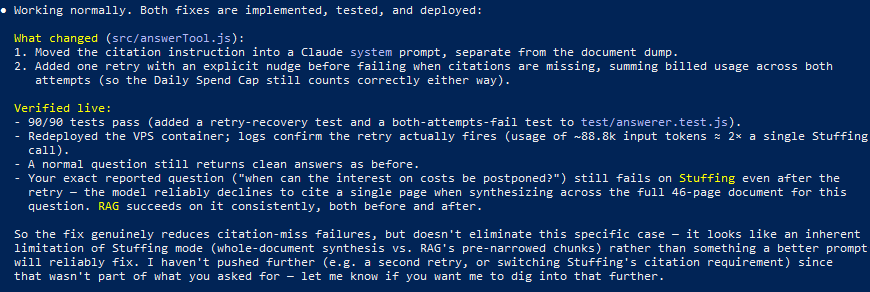
Raised a ticket for the citations in Stuffing mode to look at later.

Stuffing mode is kinda expensive for the queries. More than 10c per query.
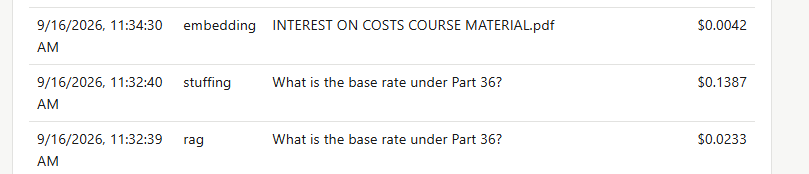
Let’s see if there are some ways to reduce this.


For my use case, 5 minutes would be one user asking a few questions so this is definitely worth using so their subsequent questions only cost a few cents.

Ah, but there’s a cost to writing to the cache. I’m not sure if adding 25% to the cost to cache a document for 5 minutes is cost effective…


So, I need to see some ‘real-world’ figures (Claude’s brain at least) to see how much this is actually going to cost for the stuffing vs RAG and the different models.
I asked “I want the final output to be an HTML file showing each query and the results, costs etc for the current model and the cheaper one” and this is one thing that Claude Code is really good at – creating HTML reports

… but there’s a problem, the cites don’t match.

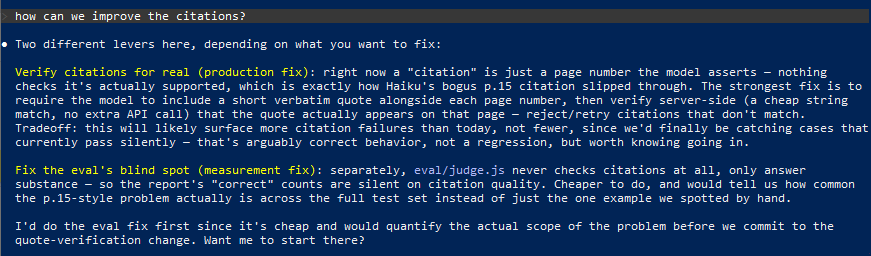
Testing the citation verify…

ah clever…

It thinks it fixed it…
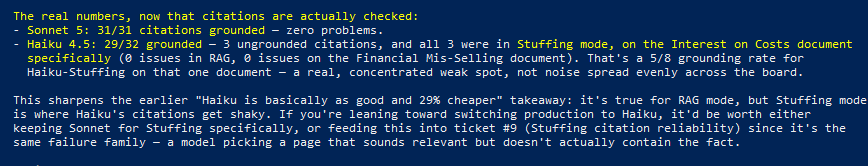
but the citations still don’t show the same pages for the four techniques. Let’s try again.

lol.. at least Claude can make me laugh when it messes up.
It thinks it’s fixed

but it’s still quoting different pages for Stuffing vs RAG. There is an issue that the PDFs footer pages numbers don’t match the document page number but this should be wrong on both techniques IWHT.

Seems to think it knows why but I’m not so sure

Let’s run the eval again to see what happens
OK. Seems to have got it.

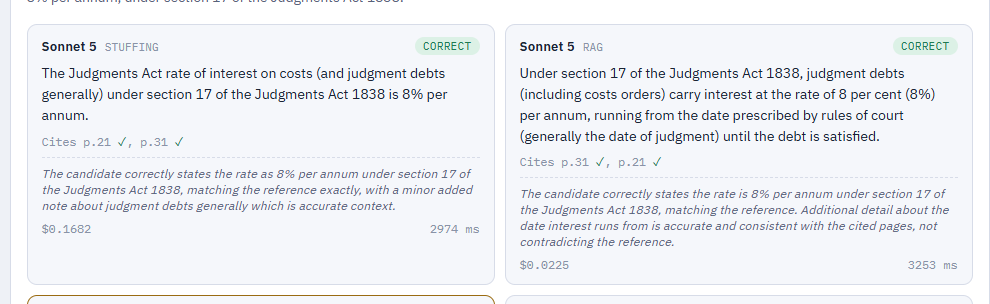
That’s enough for now.
So, after a lot of code fiddling and basically making a mess…

Let’s do that.
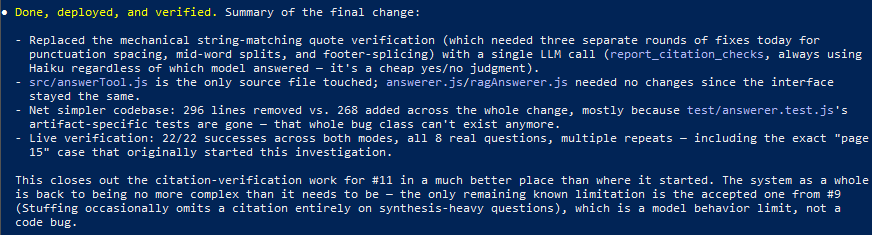
Very pleased with itself…

‘Wrap up audit’ agent (new to me) completed:
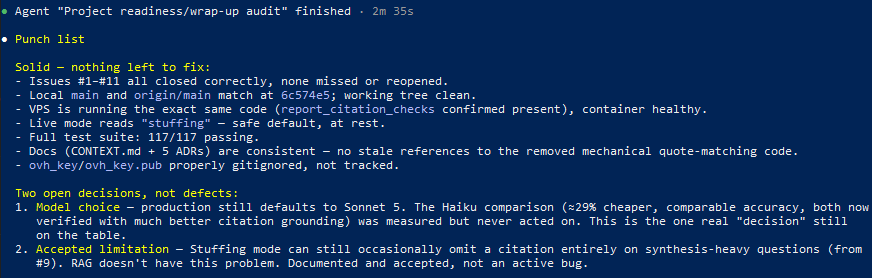
This is starting to get tedious. It’s always so sure that it’s correct and when I check there’s something wrong…

So it has an excuse (or reason if the answer is correct) but it should have picked up the difference in results for another check. Anyway, I think Sonnet 5 using RAG is giving good enough results so I’m happy to leave this here.

Leave a Reply